Spidra now returns structured data for supported pages across 17 popular websites, making it easier to work with commonly requested information.
You can retrieve product details, job listings, business information, videos, social media data, and other public records using ordinary scraping requests.
For supported pages, the returned fields are already named and organized. You don't need to define a custom prompt or schema just to get the commonly available fields.
More than page content
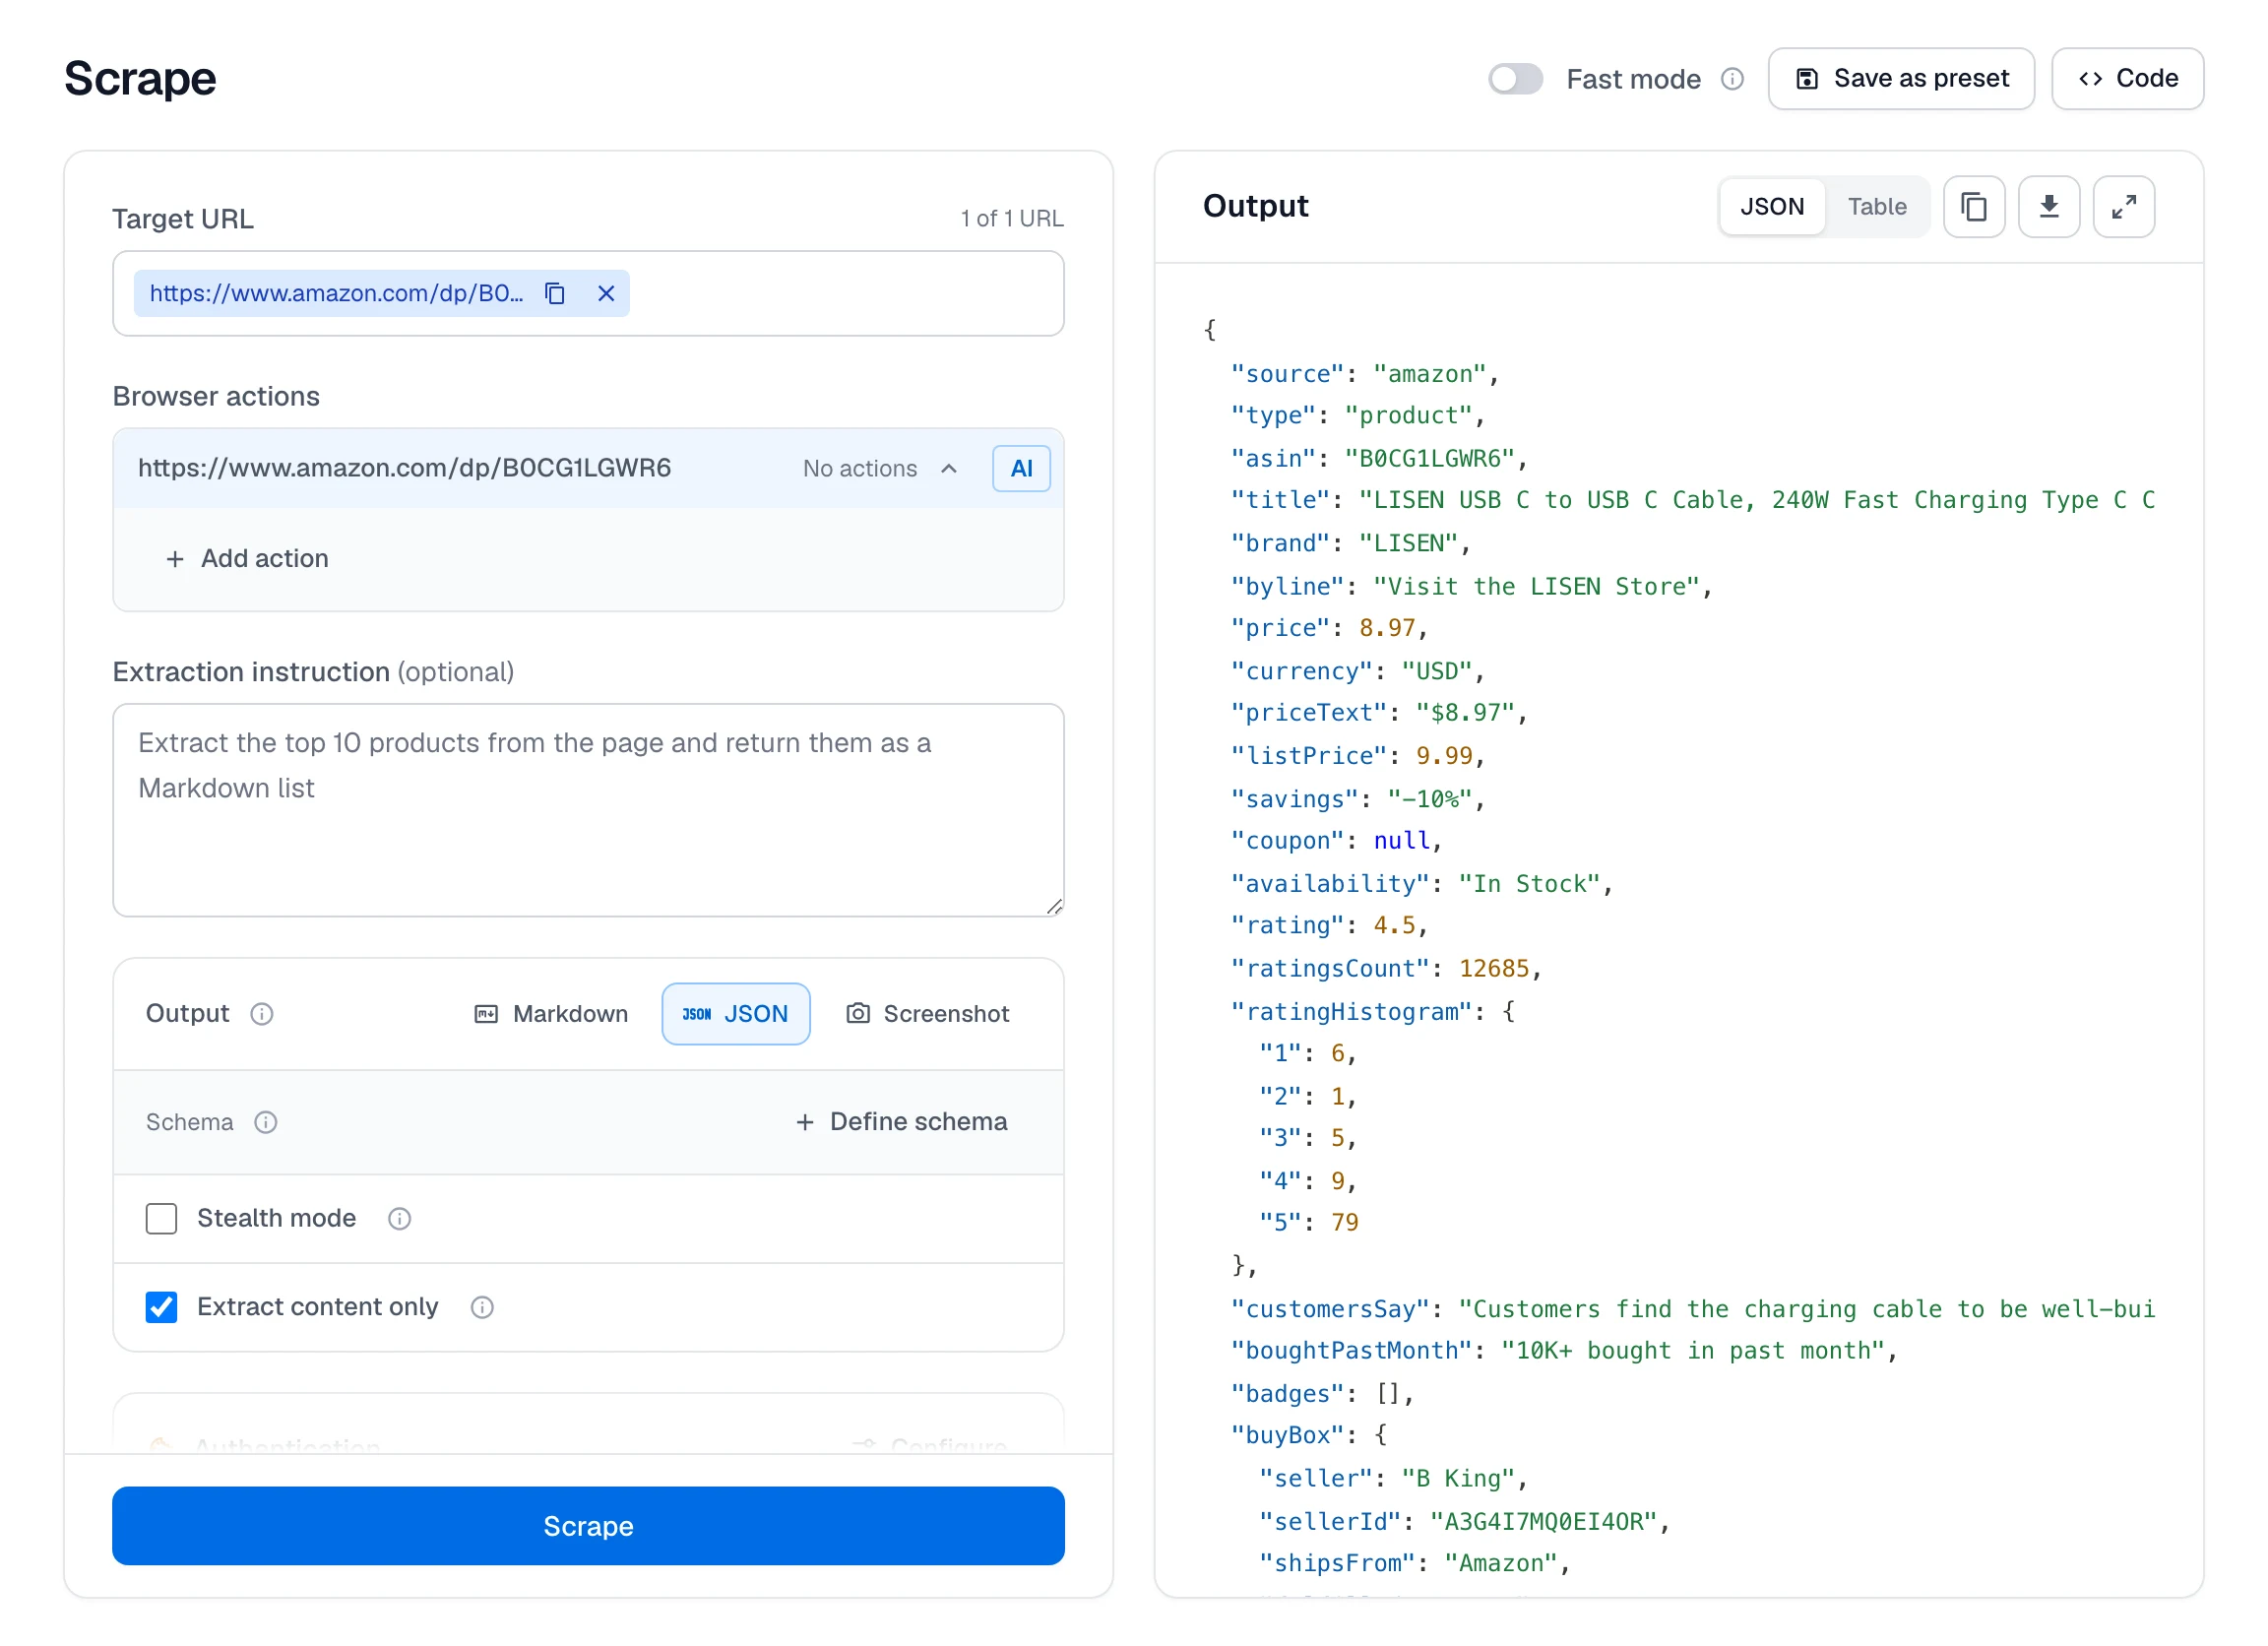
For example, scrape an Amazon product URL with JSON output and Spidra can return fields such as:
- Product title and ASIN
- Price and currency
- Availability
- Ratings and review counts
- Seller and delivery information, when available
Other supported pages include Google Maps places, Indeed job listings, LinkedIn companies and public posts, YouTube videos, Reddit discussions, Zillow properties, and more.
Use the default fields or define your own
To request the available structured fields, select JSON output and scrape a supported URL without a custom prompt or schema.
If your application needs a different structure, you can still supply an extraction prompt or JSON schema.
The available fields depend on the website and page type. Information that isn't available from the page may be returned as null or an empty collection.
This capability works through Scrape and Batch Scrape, including the API and SDKs.
See the supported popular websites and returned fields, or try a URL in Spidra.